Service 01 / 04 · AI Engineering · all services
Stop paying per token for a task that has not changed: a small model on your own server
Distill, fine-tune and deploy the smallest model that does the job, then wire it into the place your team already works.
Most AI budgets go to frontier-model API bills for tasks a 300M-parameter student can do in a second on a CPU. The work is to find that student: build the corpus, distil or fine-tune, quantize, measure against the teacher, and ship the result behind an interface your team can operate. When a smaller model does not transfer, that is a published result too, and it saves the next month of your budget.
This is the right call when
- 01
Your frontier-API bill grows every month for a task that has not changed since spring.
- 02
Your team already lives in Slack or Claude and wants the CRM, the CMS and the reports reachable from there.
- 03
You need an agent that acts on company data, with every write audited.
What you get
What lands on your account
- Eval suite on your data, with the negatives published
- The smallest model that passes it, quantized, deployed on CPU or your account
- MCP server exposing your systems as tools, one write-gated gateway
- Handoff pack: how to retrain, re-evaluate and roll back
How it runs
Three steps. The six-step version, with the brief and the video request, is on the home page.
- 01
Scoping call
30 min, freeYou describe the situation; I ask three questions and propose a shape.
- 02
Roadmap and architecture
$1,250 depositA written plan with a date. The deposit is credited to the first invoice; the documents are yours either way.
- 03
Build, handoff, operate
date on the roadmapOne engineer builds every layer on your account, documents it, and can keep operating it.
Case studies
The systems behind this service, with the numbers their owners cleared for publication.
 H2M ML Lab
Thirteen distillation experiments on real corpora. Students from 230M to 1.2B parameters, quantized, about a second on CPU.
Published negatives included: a distillation that did not transfer, and a teacher that turned out to be the cap.
- 13
- experiments
- 230M–1.2B
- student sizes
- ~1s
- CPU inference
 Adtrip
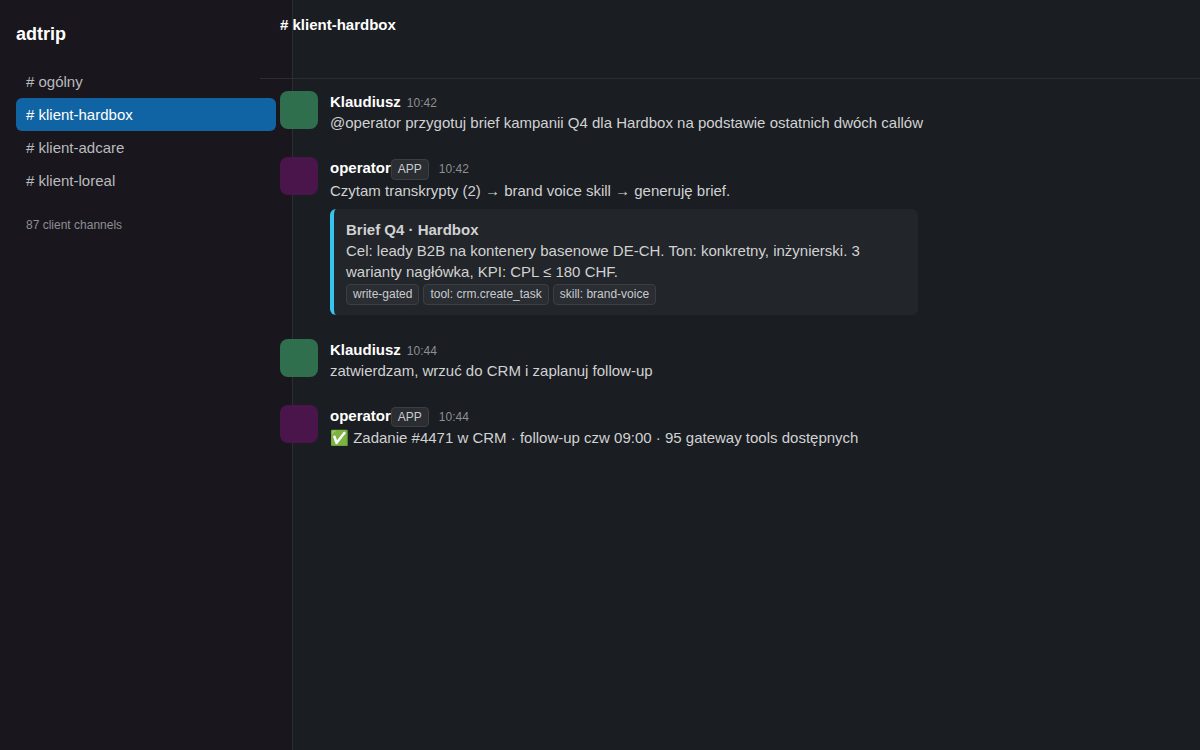
Slack-native AI operator for a 25-person agency: headless Claude Code behind one write-gated gateway.
Every write to the CRM goes through one gateway with an audit trail; the brand voice was distilled from real sales calls, not a style guide.
- 2,315
- call transcripts distilled into brand voice
- 1
- write-gated MCP gateway
 Adcare
A clinic marketing operating system operated from Claude through its own MCP server.
Multi-tenant CMS plus agency and per-clinic CRM, every action available as a tool.
- 1
- MCP server over CMS + CRM
Runs on
 Claude
 Anthropic
 MCP
 Hugging Face
 Pytorch
 Python
 Workers
 Typescript
Questions I get about this
Tap a question. The answer comes back like a text.
Scoping calls · most weeks
Whatever passes the eval on your data. Claude for agents and code; for narrow tasks often a small open model fine-tuned on your corpus and run on CPU. The comparison is published with the result.
Training corpora and fine-tuned weights stay in your storage. When a frontier API is used, it is under your own key with a written data-retention setting.
A written roadmap and an architecture for your system, delivered after the scoping call. If we build together, the full amount comes off the first invoice. If not, the documents are yours to take to anyone.
You do. The repository, the Cloudflare account, the domains and the data sit under your company from day one. I get access, not ownership.
Something else? Ask it on the call
A 30-minute call, free
Thirty minutes, then a written plan
Leave an email. I reply within one working day with three questions and a proposed plan, not a deck.